Nobody merges an email
Agents made work cheap to produce and no cheaper to check. Why software absorbed the flood, why the rest of the business did not, and the five things that make agent work checkable.
Contents
It is 5:40 on a Friday and the agent has just written nine client updates in four minutes, sitting there quietly pleased with itself. Eight of them are fine. One of them has told a client something that is not true, and because nothing in the pipeline can tell you which one, you read all nine. Forty minutes later you send eight, rewrite one, and work out that the time you saved on the writing came straight back out of your evening. The agent did not save you thirty six minutes. It moved them, out of writing, which you are decent at, and into checking, which nobody is good at and nobody enjoys.
Every tool you actually work in has an undo. Git has revert, your editor has a keystroke, staging has the comfort of breaking somewhere that does not count, and Gmail gives you thirty seconds. Nobody merges an email: there is no diff to skim, no test suite to run it past, no staging inbox to try it in, and no way back once it is sitting in somebody’s inbox, so the entire cost of being wrong lands on one person reading carefully. That gap, and not the model, is why your agent is trusted with code and kept well away from the account manager’s inbox. It is also why most agent pilots quietly stall.
The bottleneck moved and the tooling stayed put
Software is the one place where a lot of people pointed agents at real work and then measured what happened. The measurements are not subtle.
Faros AI compared two years of telemetry from 22,000 developers across 4,000 teams, looking at each organization at its lowest and highest AI adoption. Output went up. So did everything that output costs you.
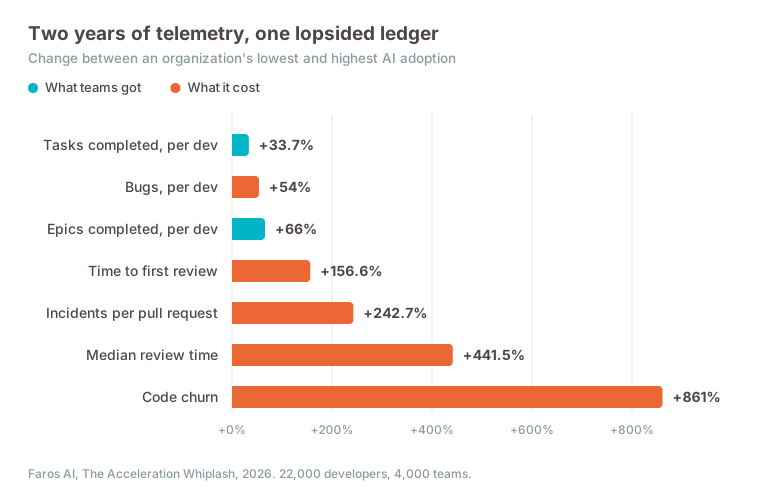
A third more tasks per developer, and five times the median review time (Faros AI, 2026). That is not a tooling problem or a model problem. That is a system that got very good at producing work and no better at absorbing it.
LinearB looked at the same squeeze from the other end, across 8.1 million pull requests from 4,800 teams in 42 countries, and found the detail that gives the game away.
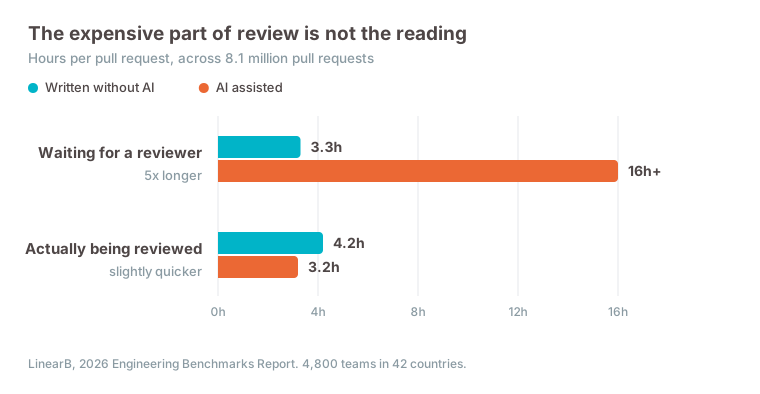
Read those two bars again. Once a reviewer actually starts, the AI-assisted change is faster to get through than the human one: 194 minutes against 252 (LinearB, 2026). The delay is not the reading. The delay is everything before the reading: the queue, the size of the thing, the sinking feeling, the decision to start.
The expensive part of verification was never the mechanical act of checking. It is the willingness to be the person who signs off.
Why software absorbed the flood anyway
Engineering took that hit and mostly kept moving, and it is worth being precise about why, because the reason is not talent or process maturity. It is that code is the most verifiable artifact a company produces, and it has been getting more verifiable for forty years.
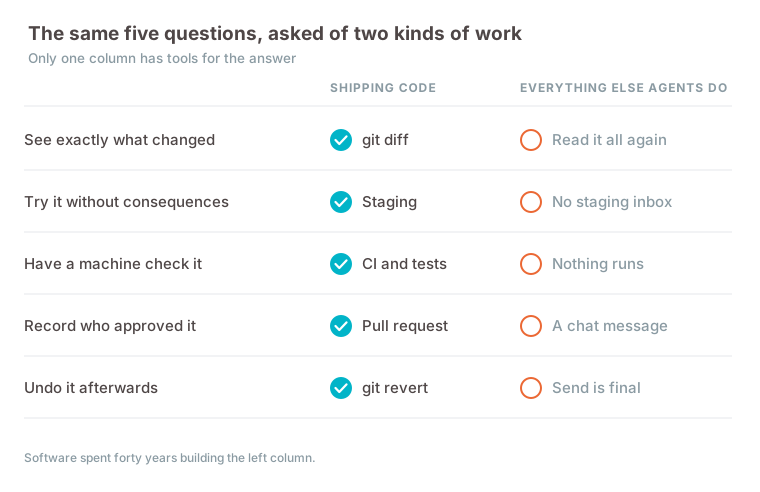
A diff is a strange and wonderful thing. It turns “read this 400 line change” into “read these 40 lines that differ”, which is a reduction of an order of magnitude in what a human has to hold in their head. Tests turn “is it correct” into a boolean somebody else already thought about. Staging turns “will this break” into “it did not break over there”. A pull request turns approval into a record with a name on it. Revert turns a mistake into an inconvenience.
None of that exists for the work most of a company actually does.
There is no diff for an email. There is no staging environment for a CRM. No test suite asserts that the invoice you generated has the right billing period on it, and no button unsends the reply to a customer.
So when an agent produces that kind of work, the verification cost lands entirely on a human with no instruments, and it lands per unit of output. Double the output, double the checking. That is the whole story of why the demo felt like magic and the rollout felt like a second job.
Read next: Your agent has a half-life
The check has to be cheaper than the doing
Here is the arithmetic nobody puts in the pitch deck.
Let D be what it costs you to do the job yourself. Let C be what it costs to check the agent’s version. Let p be the chance it is wrong in a way you would care about, and R the cost when a wrong one gets through: the apology, the refund, the client who stops replying.
Delegating pays when:
C + p x R < D
The model only appears inside p. Everything else in that inequality is a property of your tooling, and it is the part every agent roadmap ignores.
Run it on the Friday nine. Writing one yourself is about six minutes, so D is 54 minutes. Reading nine drafts closely enough to put your name on them is about four minutes each, so C is 36, which is near enough the forty you actually spent. The saving is whatever is left, and it is thin. Note where it went, too: one draft was wrong, and you paid to check nine, because nothing in the pipeline could tell you which. Now make the drafts slightly harder to trust, so you reread the source thread for each one, and C passes D. The agent is now a net loss at 100% quality, because quality was never what you were paying for.
| Work the agent finished | What you check it against | Cost to check | Cost if a bad one gets through |
|---|---|---|---|
| A code change | A diff, a test run, a staging deploy | Minutes, tool-assisted | A revert |
| Nine client emails | The nine source threads, from memory | Nearly the cost of writing them | A relationship |
| 200 CRM records updated | Nothing. You spot check twelve and hope | Unbounded, so people skip it | A quarter of bad data |
What checking costs across three kinds of agent work
Notice what happens in the bottom row. When C is unbounded, people do not pay it. They either check nothing and silently accept p x R, or they stop using the agent for that work. Both look like “the agent did not work out”. Neither is about the agent.
This is the same shape as the half-life problem: a per-step property that looks fine up close and decides everything at scale. There, it was reliability compounding over a long run. Here, it is verification cost compounding over volume. Both get fixed by changing the structure of the run, not the intelligence inside it.
Nobody is measuring this, including you
The obvious objection is that if verification were really eating the gains, people would notice.
They do not notice. That is the best-documented part of this whole argument.
METR ran a randomized controlled trial with 16 experienced open-source developers on 246 real tasks in repositories they already maintained. Before starting, the developers forecast that AI tools would make them 24% faster. Afterwards, having done the work, they believed they had been 20% faster. Measured, they took 19% longer.
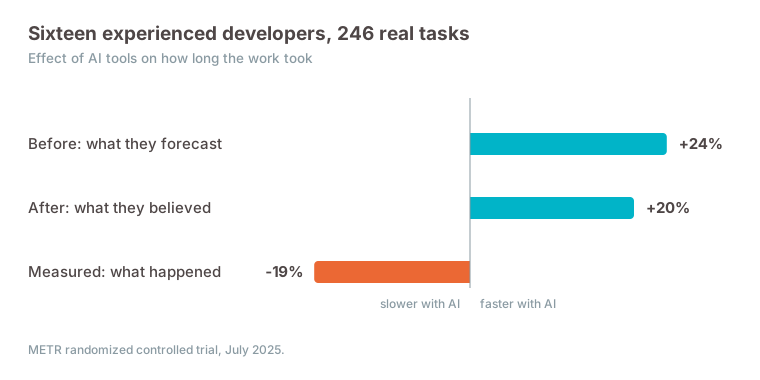
These were not novices fumbling with a new toy. Nearly all of them had dozens to hundreds of hours of prior experience prompting models (METR, July 2025). The generation felt fast, because it was. The review, the correction, the second pass to understand what had been written for them: that time was real and it did not register.
Now scale that error up to a company. MIT’s Project NANDA, working from more than 300 publicly disclosed deployments, 52 interviews, and 153 survey responses, put the share of enterprise GenAI pilots with no measurable impact on the P&L at roughly 95% (MIT NANDA, 2025). People have argued about that methodology ever since. Nobody has argued that the number is small. Gartner expects more than 40% of agentic projects to be canceled by the end of 2027, citing costs and unclear value (Gartner, June 2025). DORA, surveying nearly 5,000 professionals, landed on the phrase that ties it together: AI is an amplifier (DORA, 2025). It makes a system with good feedback loops better and a system without them worse, faster.
Most business processes have no feedback loops at all. They have a person who would notice eventually.
Agents rarely fail an evaluation. They fail an audit nobody ran.
Five things that make agent work checkable
If verification cost is the constraint, then the interesting engineering is not in the agent loop. It is in everything the agent leaves behind. Five properties do most of the work, and none of them require a better model.
Artifacts, not transcripts
A chat transcript is the worst possible verification surface: linear, long, and it buries the output inside the reasoning. A file is the best one. You can open it, skim it, diff it against last month’s, hand it to someone else, and know at a glance whether the thing exists yet.
The rule is that finished work should be an object you can point at, not a passage you have to read to the end of.
A draft state before anything irreversible
This is the missing diff, and it is mostly a product decision rather than a research problem. Generate the email, do not send it. Compute the 200 CRM updates, write them as a table first. Produce the invoice as a file before it goes to the customer.
A draft turns an irreversible action into a reviewable artifact, which moves it out of the unbounded row of that table and into the cheap one. The work is identical. The verification cost is not.
Provenance on anything the agent believes
Half of checking is not “is this right”, it is “where did this come from”. An agent that says the client’s renewal is in March is unverifiable. An agent that says the renewal is in March, learned from the contract PDF you uploaded on 14 August, can be checked in four seconds.
That is why agent memory needs provenance and correction rather than a vector blob. Memory you cannot audit is a claim you have to re-derive, which is verification cost with extra steps.
A bounded record of what it touched
Not the full trace. Nobody reads the full trace. What you need is the ledger: what did it touch, when, and why. It is the difference between a stack trace and a receipt.
The test is whether someone can answer “what did it actually do yesterday” in under a minute without reading a single model output.
Reversibility where it exists, a human where it does not
Some actions can be undone, and those should be cheap to approve. Some cannot, and pretending otherwise is how teams get burned. Sending mail, moving money, posting publicly, deleting records: for those the honest answer is that a person confirms, and the product’s job is to make that confirmation a two second glance rather than an investigation.
How Construct is built around the check
We build an AI employee with a real computer, so this is the problem we live in. A few things follow directly from the argument above.
Work lands in a workspace filesystem as files, not as messages in a thread. That is the artifacts rule, and it is also why a run that dies partway through leaves usable output behind rather than a transcript to excavate.
Every action goes into Activity: what it affected, when it ran, and why. That is the receipt, not the stack trace, and it exists so the answer to “what did it do overnight” is a scroll rather than a project. Alongside it you get the files it produced, the tool records, and a read-only terminal transcript when you want to go deeper.
Memory is inspectable and correctable, with provenance and temporal context, so a claim can be traced to where it came from and fixed in place instead of argued with. Repeatable work becomes a saved workflow you can read before you schedule it. Current workflows are linear, which is a real limitation and also the reason a workflow is something you can hold in your head.
And the part we have not finished: Construct does not currently insert a mandatory approval gate before every external side effect. Drafts, interruption mid-run, and Activity give you a lot, but if a step sends a customer email or moves money, that step still needs supervision before you let it run unattended. We would rather say that plainly than let someone discover it on a Sunday.
The next 10x is not in the model
Every agent product is currently competing on the part that got commoditized. Producing plausible work is close to free and getting freer.
The scarce thing is a human’s willingness to sign their name under it, and that is bought with diffs, drafts, receipts, provenance, and undo. Software has had those for forty years and, funnily enough, software is the one place agents are actually working.
The rest of the company is waiting for someone to build them the other column.
Originally posted on construct.computer.